Sign up with Google
 Sign in with Zoho
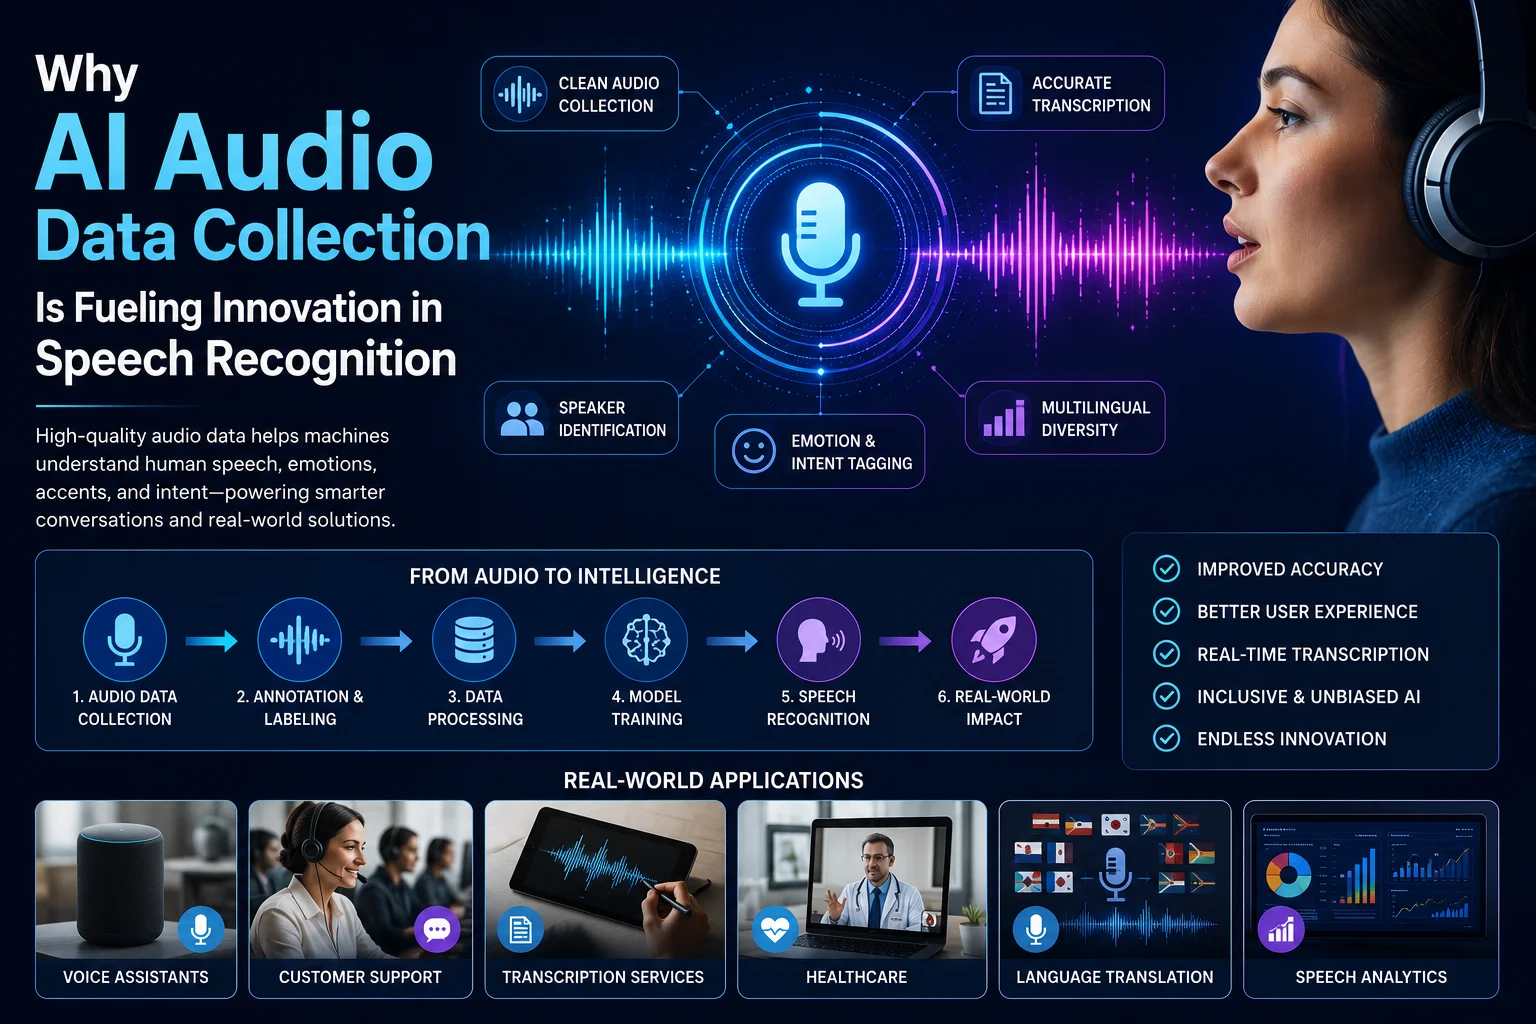
Artificial intelligence is transforming how businesses operate, automate tasks, and make decisions. From healthcare and retail to finance and transportation, AI-powered solutions are helping organizations improve efficiency and deliver better customer experiences. However, the success of any AI model depends heavily on the quality of the data used to train it.
Training Data Collection for AI is a critical step in developing accurate, reliable, and scalable machine learning systems. Without relevant, diverse, and properly labeled data, even advanced AI models can produce inaccurate predictions. Businesses that prioritize data quality can improve model performance and build AI solutions that meet real-world requirements.
In this guide, we explore practical steps for building high-quality AI training datasets and explain how working with an experienced AI Training Data Company can support your AI development goals.
Why High-Quality Training Data Matters
AI models learn patterns from the examples provided during training. If those examples contain errors, inconsistencies, or bias, the model may learn incorrect patterns and generate unreliable results.
High-quality training data helps businesses improve prediction accuracy, reduce model errors, and develop AI applications that perform consistently across different scenarios.
For example, an AI-powered retail application needs relevant product images and accurate labels to recognize products correctly. Similarly, a natural language processing system requires well-structured text data to understand user queries and generate meaningful responses.
The Impact of Poor-Quality Data
Low-quality datasets can create several challenges, including:
- Inaccurate AI predictions and classifications.
- Biased outcomes caused by unrepresentative data.
- Increased development costs due to repeated data cleaning.
- Poor performance in real-world environments.
- Delays in AI model training and deployment.
Investing in reliable Training Data Collection for AI helps organizations address these challenges before they affect production systems.
Step 1: Define Clear AI Training Objectives
Before collecting data, identify what your AI model needs to accomplish. Your objectives determine the type, volume, format, and quality of the data required.
For example, an image recognition model requires labeled images, while a speech recognition system needs audio recordings paired with accurate transcripts.
Identify the Right Data Requirements
Start by defining the following elements:
- The AI application and its intended purpose.
- The types of data required, such as text, images, video, or audio.
- The target users and operating environments.
- The labeling and annotation requirements.
- The performance standards for the finished model.
Clear requirements help teams avoid collecting irrelevant information and ensure that every dataset supports a specific business objective.
Step 2: Collect Relevant and Diverse Data
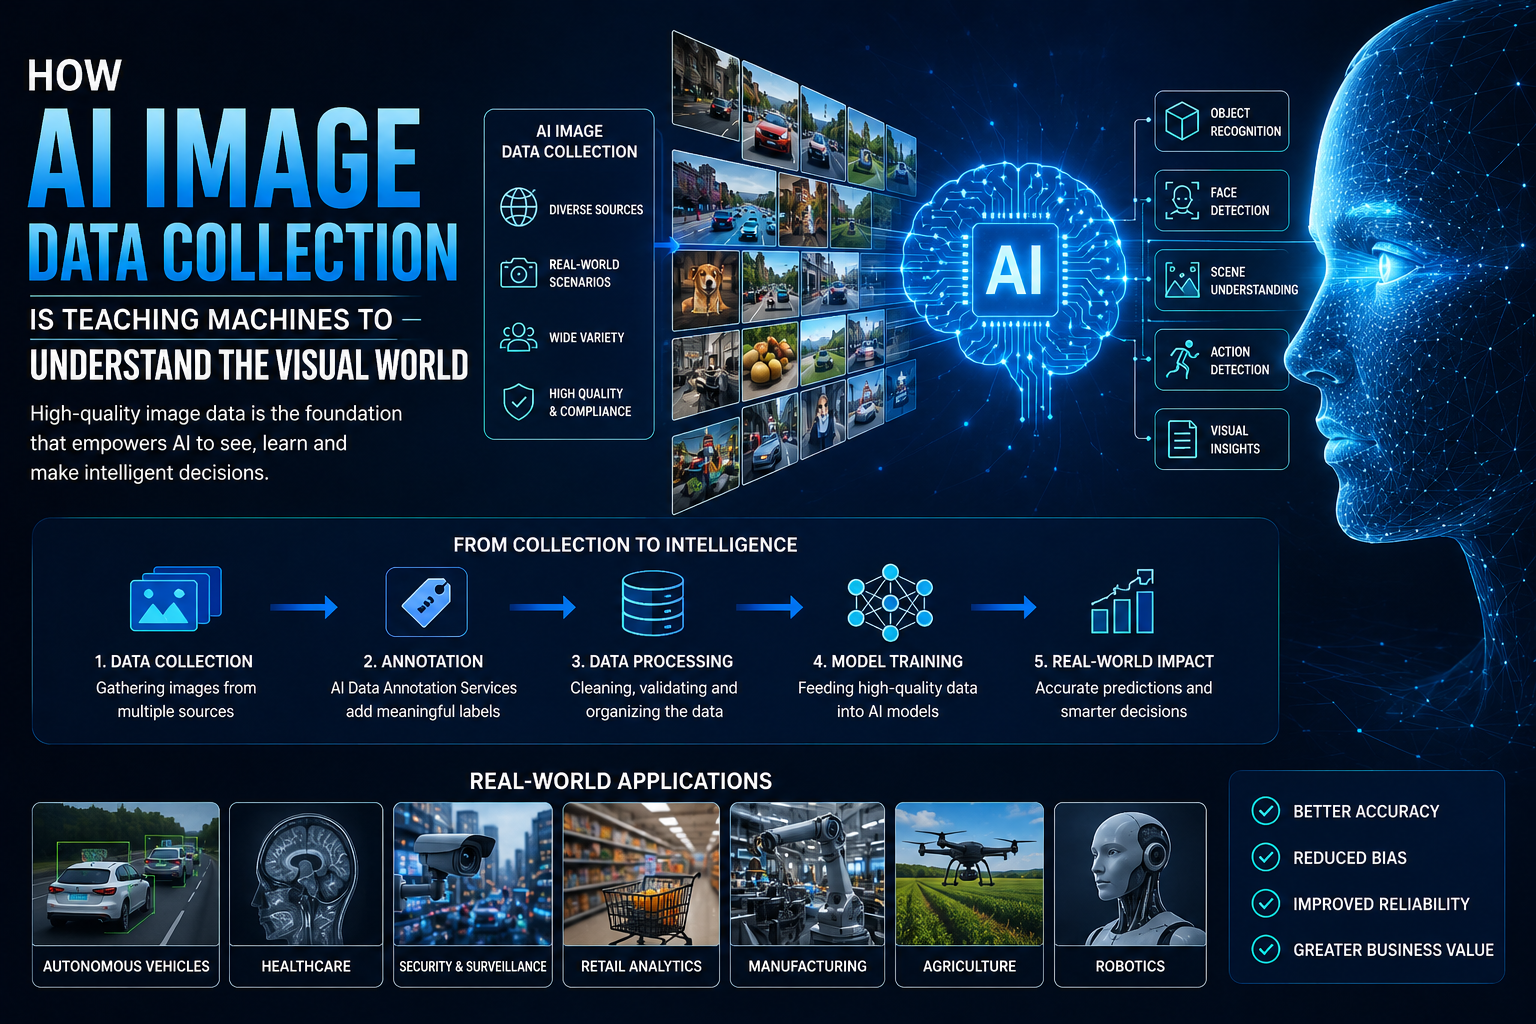
Data diversity is essential for building AI models that perform reliably beyond controlled testing environments. A dataset should represent the different conditions the model may encounter after deployment.
For example, a computer vision application may require images with different backgrounds, lighting conditions, camera angles, and object variations. An AI chatbot may need text examples covering different questions, writing styles, and customer scenarios.
Use Reliable Data Sources
Businesses can collect training data from several sources, including proprietary datasets, licensed third-party information, public datasets, and human-generated examples. Synthetic data may also help fill certain gaps when real-world examples are limited.
However, every source should be evaluated for relevance, accuracy, permitted usage, and potential bias. Appropriate consent, licensing, and privacy safeguards should be maintained throughout the collection process.
Step 3: Clean and Organize Your Dataset
Raw data often contains duplicate records, incomplete entries, irrelevant information, formatting problems, and inconsistencies. Using this information without proper preparation can negatively affect model performance.
Data cleaning ensures that datasets are organized, consistent, and suitable for training.
Establish Data Cleaning Standards
A reliable cleaning process should include:
- Removing unnecessary duplicate records.
- Identifying missing or invalid information.
- Standardizing formats and naming conventions.
- Checking image, audio, video, and text quality.
- Reviewing data for inconsistencies and potential bias.
Well-organized datasets are easier to maintain, validate, and update as AI projects evolve.
Step 4: Apply Accurate Data Annotation
Data annotation adds labels or contextual information that helps supervised machine learning models understand the examples they receive.
For instance, image annotation may involve drawing bounding boxes around objects, while text annotation may classify customer sentiment or identify named entities. Video annotation can track moving objects, and audio annotation can include speech transcription and speaker identification.
Maintain Consistent Annotation Guidelines
Create clear instructions for annotators and establish quality benchmarks. Human reviewers should evaluate samples regularly to identify labeling mistakes and resolve ambiguous cases.
Combining trained human annotators with appropriate automated tools can improve efficiency without sacrificing accuracy.
An experienced AI Training Data Company can help businesses develop annotation workflows that align with their model requirements and industry-specific use cases.
Step 5: Validate Data Quality Before Training
Data validation helps confirm that the dataset meets established standards before it enters the model-training pipeline.
Quality checks should examine completeness, labeling accuracy, consistency, diversity, and suitability for the intended application.
Create a Continuous Quality Assurance Process
Use automated checks to detect formatting errors and duplicates, supported by human reviews for complex or ambiguous examples. Track recurring issues and update collection guidelines when necessary.
Organizations should also maintain separate training, validation, and test datasets. These datasets must be separated carefully to reduce data leakage and provide a more realistic evaluation of model performance.
Step 6: Protect Data Privacy and Security
High-quality training data must also be collected and managed responsibly. Businesses should consider applicable U.S. privacy laws, contractual requirements, and industry-specific regulations when handling personal or sensitive information.
Use appropriate access controls, secure storage, retention policies, and data minimization practices. Documenting data sources and processing steps also improves transparency and supports future audits.
Partner With the Right AI Training Data Company
Building a high-quality dataset requires planning, technical expertise, annotation resources, and consistent quality control. For businesses managing complex AI projects, working with a specialized AI Training Data Company can help streamline data collection and scale operations as requirements grow.
Look for a partner with experience across relevant data types, transparent quality assurance processes, flexible workflows, and strong data security practices. The right provider should understand your AI objectives and deliver datasets tailored to your specific requirements.
Conclusion
Building high-quality AI datasets requires more than gathering large amounts of information. It involves defining clear objectives, collecting diverse data, cleaning raw information, applying accurate annotations, validating quality, and protecting privacy.
A structured approach to Training Data Collection for AI helps businesses create dependable datasets that support more accurate and effective AI applications.
OneTech Solutions can help businesses strengthen their AI development workflows with data collection and annotation support for different project requirements. Visit onetechsolutions.ai to explore how a reliable training data strategy can support your next AI initiative.