 Sign up with Google
 Sign in with Zoho
A 2019 field study compared Facebook advertising experiments and found that observational methods often failed to match randomized results. That is why a visible competitor ad should never carry the same weight as a clean result from your own account.
Competitor ads should influence a Meta creative test queue when they reveal a repeated, relevant market pattern or an untested messaging gap. They should not outrank clear first-party conversion evidence, predict a guaranteed winner, or turn ad longevity into proof of performance. Use external activity to form hypotheses, then validate them with a controlled account-level test.
We will show how to rank concepts, launch fair tests, classify bad data, and preserve the learning so next week’s queue gets smarter.
What Can AI Really Predict in a Meta Creative Test Queue?
AI can make the planning stage dramatically more useful without making it magical. We use it to organize incoming concepts, identify repeated customer language, compare creative tags with prior results, find untested angles, and explain why an idea belongs near the top of the queue.
What it cannot do is know whether an unlaunched concept will produce profitable or incremental conversions. A rank is a recommendation about where to learn first, not a performance forecast. The useful distinction is simple: prediction can help prioritize, but testing establishes what happened in your account under specific conditions.
Rank Hypotheses, Not Winners
A strong AI-assisted queue gives every concept a rationale: the relevant first-party result, customer objection, external pattern, previous failure, or current gap it addresses. It should also state what would disprove the hypothesis.
Research involving Meta advertisers has shown the value of conversion signals for advertising delivery outcomes. That supports using conversion feedback in planning, but it does not prove that a model can foresee how a new hook, offer, or visual will perform.
Require Inputs That Can Explain the Rank
A useful queue combines account-level conversion performance, past experiments, creative tags, customer feedback, product changes, and external observations. We also recommend tracking which angle, proof type, format, offer, landing page, audience, and placement each test used.
That detail is what lets a team move beyond raw ROAS. Our Deepsolv creative intelligence workflow helps connect a result to the message behind it, rather than treating every creative as an isolated asset.
Keep the Guarantee Out of the Interface
Never present a score as “this ad will win.” Show the evidence sources, their recency, their confidence level, and the test needed to validate the recommendation. A human should always be able to challenge a ranking, change a weight, or reject a concept that conflicts with brand, legal, or merchandising reality.
When Should Competitor Ads Affect the Queue?
External ads belong in planning when they show a pattern worth testing in your own voice. One active creative is usually just an observation. A repeated framing, a sequence of iterations, or a notable offer shift can be a useful prompt to ask, “Is this a customer need we have not tested?”
Public ad libraries can make active ads and their start dates observable, with updates generally appearing relatively quickly. They do not reveal whether a commercial ad is profitable, incrementally effective, reaching your audience, or still active for reasons unrelated to its creative quality.
Turn Longevity into a Testable Hypothesis
Longevity is most useful when it is paired with repetition and relevance. If several relevant advertisers repeatedly use the same product demonstration, objection, or offer structure over successive checks, frame it as a hypothesis.
For example: “A concise routine-led hook may earn qualified attention because this problem is visibly central in the category.”
Our Deepsolv continuous monitoring workflow is designed to capture changes over time, not to turn any single external asset into a verdict.
Use a Source-Confidence Hierarchy
Internal conversion evidence and external ad activity answer different questions. The first helps answer what has worked in your account. The second helps answer what may be worth investigating.
A useful rule follows from that table: an external-only idea cannot earn high confidence or outrank a strong conversion-backed concept. For a deeper view of the tradeoff, use Deepsolv to compare performance signals with competitor observations before deciding what gets production time.
How Should You Rank 40 Creative Concepts Each Week?
When a DTC team has 40 concepts in design files, the answer is not to launch all of them. The queue should identify the concepts that have the best balance of potential impact, evidence quality, novelty, production feasibility, recency, and learning value.
We start by separating the score from the evidence. A concept can have a high potential impact but low confidence. That is not a defect, it is a reason to label it as a challenger rather than quietly presenting it as a likely winner.
Use a Transparent Scoring Worksheet
Use a one-to-five score for each criterion, then agree weights that match the account’s immediate goal. The starting weights below emphasize impact and confidence, but we expect teams to adjust them deliberately.
The priority score is the weighted total divided by five. Keep source confidence visible beside it, because a score alone can hide the difference between a conversion-backed idea and a market-led hypothesis. Our Deepsolv test prioritization workflow covers how to turn this worksheet into a repeatable operating rhythm.
Work Through One Concept Before Launching It
Imagine a routine-led video hook supported by recent customer comments and a repeated market pattern, but with no prior conversion test in the account. Score impact at four, confidence at two, novelty at four, inverse production effort at four, recency at five, and learning value at five.
Using the starting weights, the calculation is 76 out of 100. That makes it a sensible high-learning challenger, not a predicted winner. It should compete for a place in the next test round, while a conversion-backed concept can still rank above it.
Run a Five-Step Weekly Workflow
- Intake concepts and remove duplicates.
- Attach conversion, customer, past-test, and external evidence.
- Score each concept and label its evidence confidence.
- Launch only the concepts the available budget can evaluate fairly.
- Read out results, classify execution quality, and update memory.
This workflow creates a decision trail. It also stops teams from rediscovering the same idea every Monday without knowing whether it was already tested, rejected, or invalidated by a setup problem.
How Do You Launch and Read a Test Without Misreading It?
A queue creates priorities, but test design determines whether the result is usable. Before launch, choose whether you are exploring broad concepts or validating a single variable. These are different jobs and should lead to different conclusions.
For concept discovery, compare distinct angles against a control and decide which direction deserves a follow-up. For variable validation, change one named element while holding the audience, offer, optimization event, landing page, timing, and core setup as consistent as practical. We use Deepsolv to support stop-policy decisions that protect budget without pretending every early result is conclusive.
Set a Viability Gate Before Selecting Concepts
An $80k-per-month account should not use a generic rule for how many concepts to launch. Start with the planned test budget, expected cost per conversion, and the amount of evidence required to make a decision. If the budget cannot give each concept a fair evaluation, reduce the number of concurrent tests.
Platform optimization guidance around conversion events can provide useful context, but it should not be treated as a universal threshold for every creative decision.
Pass a Readout-Integrity Gate
Before declaring a winner, confirm that each variant was approved, rendered properly, received meaningful delivery, fired the intended conversion event, and ran under the planned settings. If a check fails, the creative did not necessarily lose. The test may be technically invalid.
Review and learning-phase considerations make approval status, delivery, tracking, and edit history important parts of the readout rather than forgotten launch checklist items.
Classify the Result Before Writing the Learning
When the issue is operational rather than strategic, a clear Deepsolv failure diagnosis workflow helps prevent teams from recording a broken execution as a failed idea.
How Does Testing Memory Improve Next Week’s Queue?
A memory system is not a folder of screenshots and final ROAS numbers. It is a structured record that lets the next ranking understand why an idea was tested, what changed, whether the setup was sound, and what the result actually means.
Good AI governance principles emphasize validity, reliability, transparency, and accountability in AI-supported decisions. For creative testing, that means keeping enough context that a future recommendation can be checked instead of accepted on blind trust.
Record the Complete Learning
Each record should include:
- Concept And Hypothesis: The claimed customer insight or performance expectation.
- Evidence Sources: Conversion history, customer signals, external observations, and their confidence.
- Test Conditions: Control, changed variables, offer, audience, placements, landing page, optimization event, dates, and spend.
- Execution Quality: Approval, tracking, rendering, delivery, edit history, and known confounds.
- Result And Reason: Valid win, valid loss, invalid result, insufficient evidence, or inconclusive outcome.
- Next Decision: Scale, iterate, retest, reject, or wait for new evidence.
Build a Defensible Queue with Deepsolv
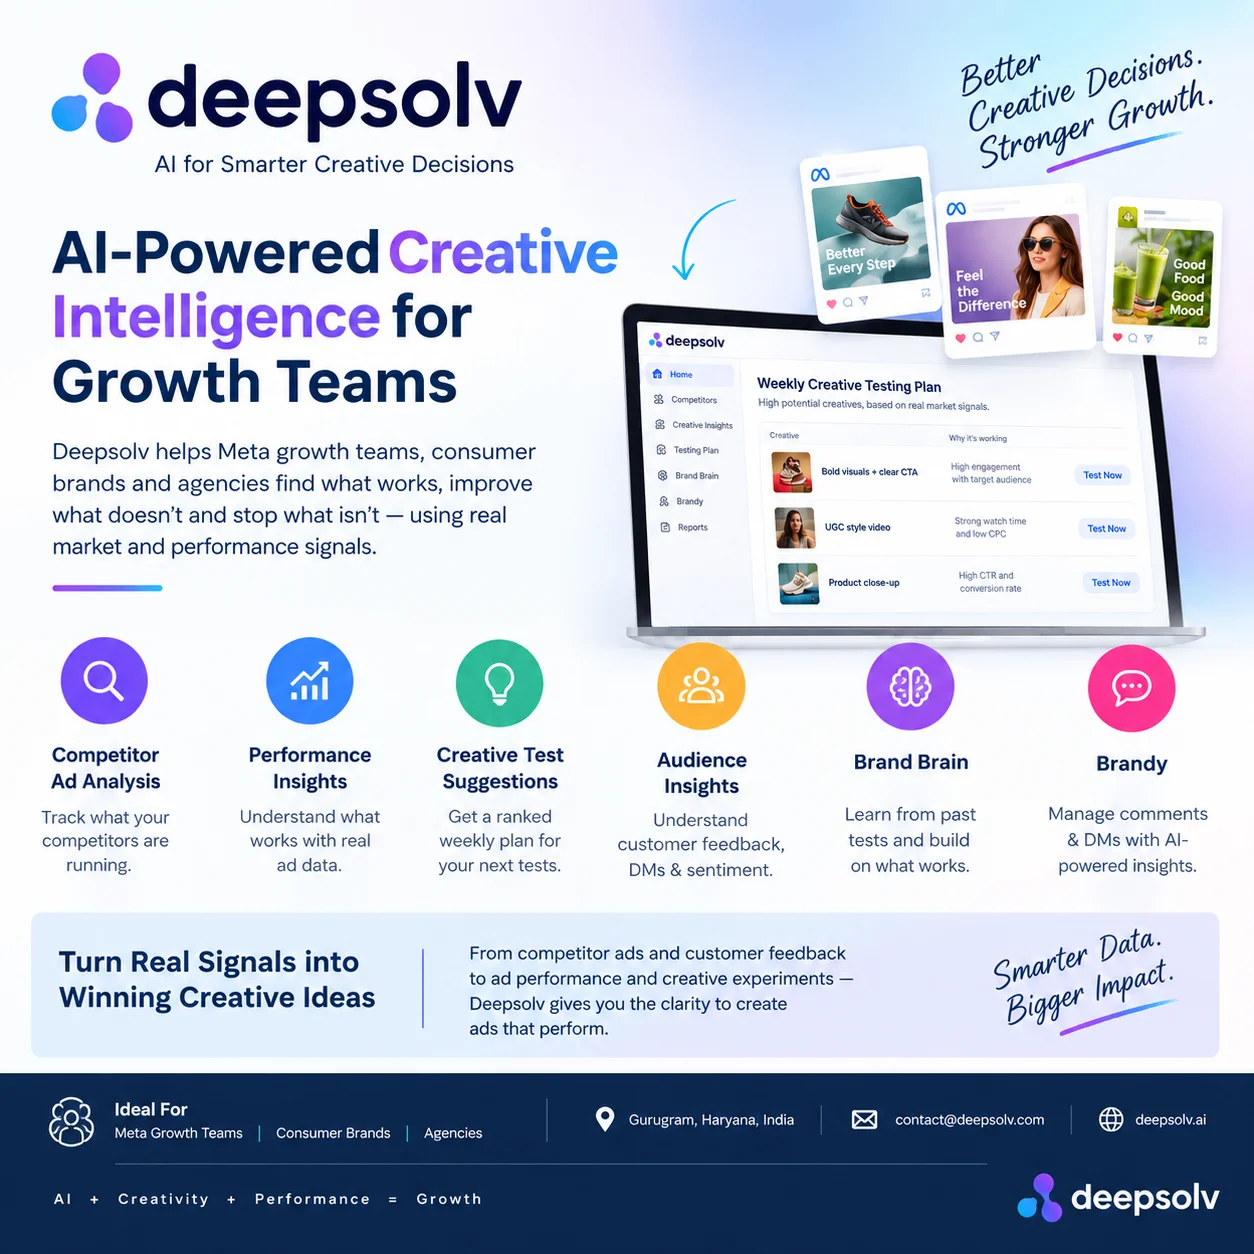
At Deepsolv, we built our workflow for teams that need a defensible decision before they spend, not another black-box score. We connect market observation, creative concepts, account performance, customer feedback, and test history so your weekly queue shows the evidence behind every recommendation.
Our system keeps external ads in their proper role: a source of hypotheses, not a substitute for conversion proof. It also preserves the operational details that usually disappear after a test, including execution issues, delivery gaps, warnings, and inconclusive results.
That gives media buyers, creative leads, and founders a shared record of what was tested, what happened, and what should happen next. If your team is managing a fast-moving Meta account, we can help turn scattered signals into an accountable testing rhythm. We make the rationale available before launch and the learning reusable afterward.
FAQs on Meta Creative Test Queue
These answers clarify queue decisions. They keep external signals in context.
Can AI Predict Which Meta Creative Will Win?
AI can rank hypotheses from your account, customer, and market inputs, but it cannot promise a winner. We validate recommendations through controlled, properly measured tests.
Does a Long-Running External Ad Prove It Performs Well?
Repeated external ads can justify a hypothesis when the pattern is relevant and recent. They cannot demonstrate spending, conversion performance, profitability, or incremental impact for your account.
What Makes a Meta Creative Test Technically Invalid?
Mark a result invalid when tracking, destination, rendering, approval, delivery, or settings failed. Fix the condition, document it, and rerun rather than recording a creative loss.
How Many Concepts Should a Team Launch at Once?
Limit concurrent concepts to the number your planned spend and expected conversions can evaluate fairly. A queue should preserve learning quality, not maximize the number launched.