 Sign up with Google
 Sign in with Zoho
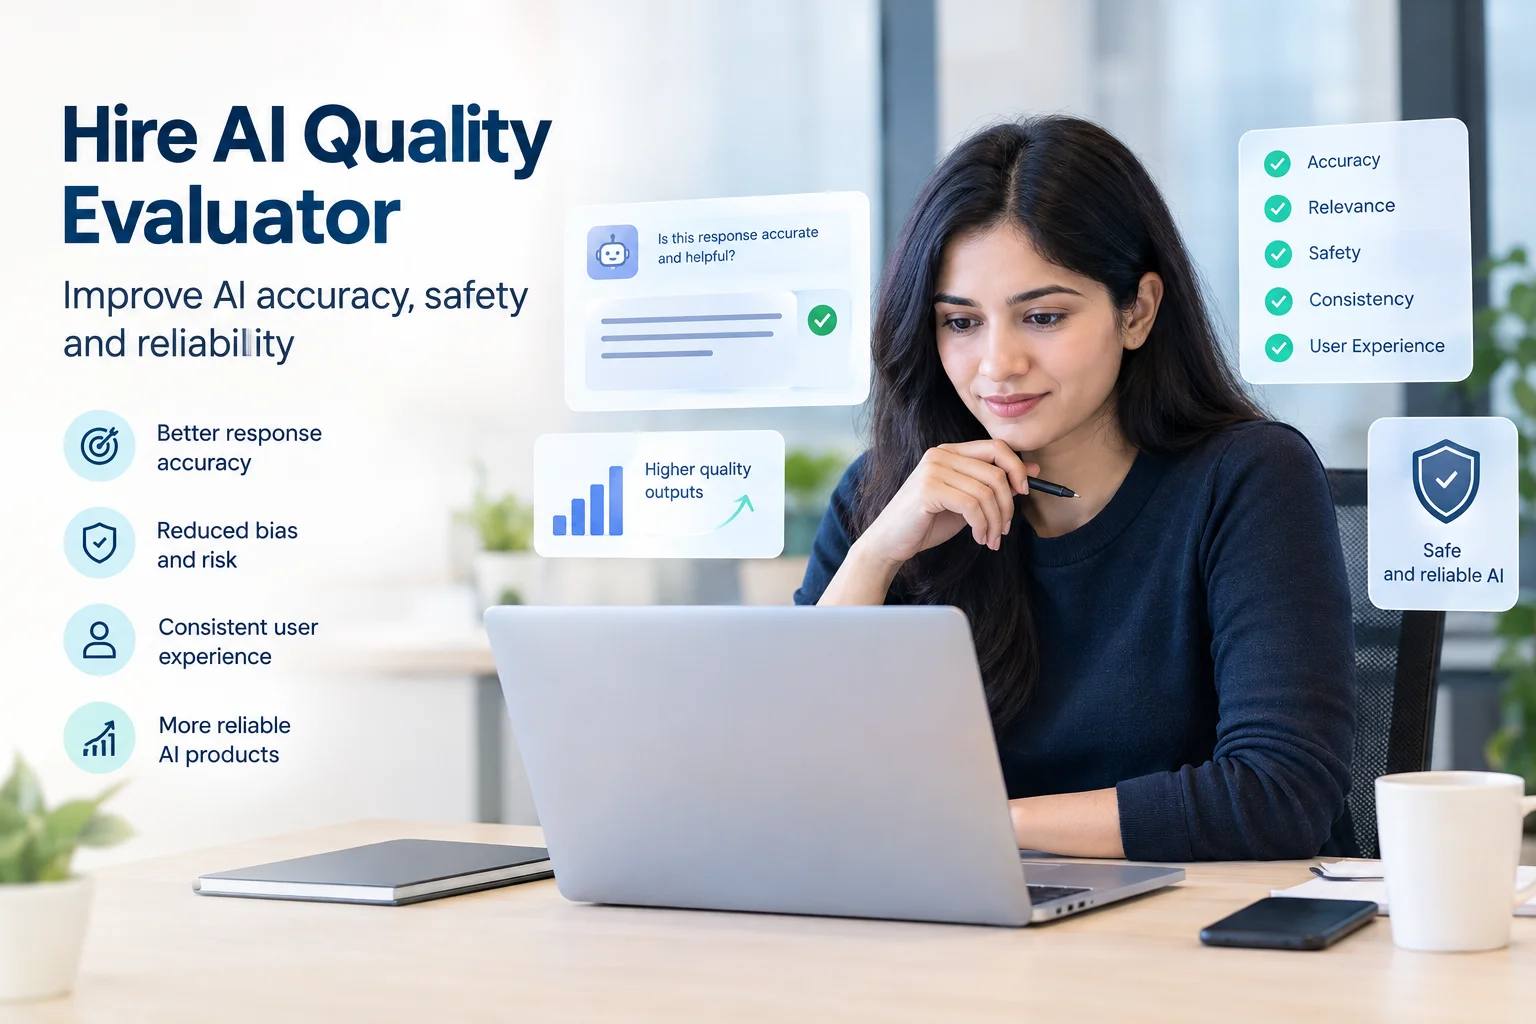
Hire AI Quality Evaluator to Improve AI Accuracy, Safety and Reliability
As AI becomes part of customer service, software products, analytics and business operations, quality has become a key product development priority. Businesses are no longer measuring AI only by whether a model produces an answer. They also need to know whether that answer is accurate, relevant, safe, consistent and useful.
This is why organisations increasingly Hire AI Quality Evaluator professionals to assess AI systems before and after deployment. Their work connects model performance with real user expectations, helping product and engineering teams identify weaknesses that automated testing may miss.
Why AI Quality Evaluation Matters
Traditional software testing usually checks whether a defined function works correctly. AI systems are different because their outputs can change based on context, prompts, data and model behaviour.
An AI Quality Evaluator can assess several important areas:
- Response accuracy and relevance
- Hallucinations and factual errors
- Bias and harmful outputs
- Instruction following
- Consistency across similar prompts
- User experience
- Performance across different use cases
For example, an AI assistant may produce technically correct information but present it in a way that does not meet the user's needs. Human evaluation can identify these practical quality issues.
The Role in AI Product Development
When companies Hire AI Quality Evaluator specialists early in development, quality evaluation can become part of the product lifecycle instead of being treated as a final-stage inspection.
Hire AI Quality Evaluator
A structured process can include creating evaluation datasets, developing test scenarios, reviewing AI responses and assigning quality scores. Evaluators can then work alongside developers and product managers to identify recurring problems.
For example, imagine an AI support tool produces 1,000 responses during testing and 8% contain factual or contextual issues. The development team can investigate those failures and test changes to prompts, retrieval systems or model configuration.
Repeating the same evaluation after improvements provides measurable evidence of whether product quality has changed.
Human Evaluation Versus Automated Testing
Automated testing is useful because it can assess large volumes of AI outputs quickly. However, automated systems may struggle with context, tone, intent and subjective quality.
Human evaluation provides another layer of understanding. An evaluator can determine whether an AI response actually addresses the user's question, follows the intended tone and provides useful information.
For many AI products, combining automated checks with human evaluation creates a more practical quality framework. Automation provides scale, while human reviewers provide contextual judgement.
What Businesses Should Measure
Before they Hire AI Quality Evaluator professionals, decision makers should define what quality means for their particular product.
A financial AI assistant may prioritise factual accuracy, consistency and regulatory requirements. A customer support chatbot may focus more on relevance, tone and successful issue resolution. An AI content platform may measure originality, consistency and adherence to brand guidelines.
Useful evaluation metrics can include accuracy rate, error rate, relevance score, instruction-following rate and human preference rate.
Even relatively small improvements can have a significant operational effect. For example, reducing problematic responses from 5% to 2% across 100,000 interactions would mean 3,000 fewer problematic outputs.
Supporting More Reliable AI Products
The decision to Hire AI Quality Evaluator professionals reflects a broader change in how organisations develop AI products. Quality is increasingly becoming an ongoing measurement process rather than a one-time testing activity.
AI models, prompts, datasets and retrieval systems can change over time. Each change can introduce new failure patterns. Continuous evaluation helps development teams identify these issues earlier and make decisions based on measurable evidence.
For technology leaders, AI quality evaluation is therefore more than finding errors. It provides practical insight into how an AI product behaves in real scenarios, where improvements are required and whether development changes are producing better outcomes.
As AI adoption continues to grow, organisations that build structured evaluation into product development can create stronger foundations for accuracy, reliability, safety and long-term user trust.
.webp)