Sign up with Google
 Sign in with Zoho
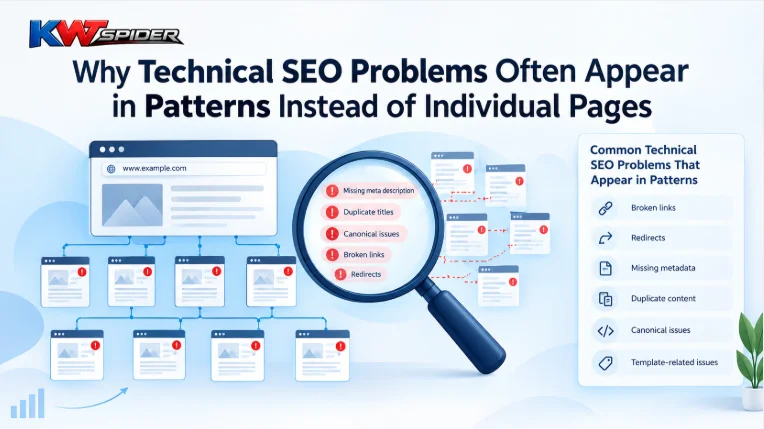
Technical SEO problems that appear on one page can often affect many other pages. Many websites have the same issue across dozens, hundreds, or thousands of URLs. Lack of meta descriptions can be a template difficulty. A group of incorrect canonical tags may come from the same template or implementation rules. A collection of redirects can indicate the previous URL size. That’s why checking individual pages isn’t always enough to understand the technical health of a website. Running a full site crawl provides a comprehensive view. Instead of examining pages separately, it reveals consistent patterns throughout the website. These patterns can display where the problem started, how widely it affects the network, and whether or not the trouble is remote or structural.
Individual Errors Can Hide a Larger Problem
Finding a single page with a missing identity doesn’t mean it’s now a first-class search engine marketing trouble. It might just be an oversight. However, it tells an extraordinary story to find loads of pages without titles. The same applies to different technical factors. A few damaged links may be a result of previous content, even as a mass of damaged links should indicate a nuisance to web page navigation, templates, or URL size. The difference is scale. When the same errors show up again and again, they routinely point to a common cause instead of separate errors. A crawl makes these patterns easier to identify because the same data can be analyzed across the entire website.
Repeated Metadata Problems Often Come From Templates
Large websites typically rely on templates to generate page titles, meta descriptions, titles, and other elements. This makes publishing content less difficult, yet it also brings it closer to the fact that trouble with one template can have an effect on many URLs.
Duplicate Titles
If hundreds of product pages use the same identity structure, which includes the product call, the problem is not always limited to 1 web page. It probably has to do with how the titles are generated.
Missing Meta Descriptions
A missing description across an entire section may suggest that a template or content field is not being populated correctly.
Repeated Headings
Similar patterns can be seen in the H1 titles. A website can also accidentally generate the same title on a couple of pages when dynamic content doesn’t always blend in nicely. It can help the crawler be aware of these styles rather than treating each affected URL as a separate nuisance.
Canonical Problems Can Reveal Structural Issues
Canonical tags are another area where recurring patterns can reveal larger problems. An incorrect canonical URL deserves interest. However, if the weight of the pages indicates an incorrect canonical destination, the problem may be deeper. For example, the template should automatically assign the same canonical URL to the entire organization of pages. Alternatively, URL parameters create variations that are not consistently handled.
Why the Pattern Matters
Looking at an affected URL can show that its canonical tag is incorrect. Viewing the entire crawl can demonstrate that the same rule affects the entire list, content type, or page template. That adjusts the method. For my part, instead of correcting the pages, one can investigate the underlying implementation.
Redirects Can Expose Outdated URL Structures
While redirects are useful when URLs do business, a large number of redirects can be tracked to see how the website has evolved. The crawl can show repeated redirects from the old list to the new list, more than one hop in the URL, or even internal links that still factor into the redirected pages.
One Redirect vs Hundreds of Redirects
A single redirect is rarely concerning by itself. A large organization of redirects from a single segment can also indicate an old URL structure that has by no means been fully cleaned up. Redirect chains can also appear when URLs have changed in a couple of instances. The important point is not that redirects exist. It's just where they arise and how often the same pattern appears.
Status Codes Become More Useful at Scale
HTTP status codes provide another clear example of why patterns matter. A 404 network can be harmless. Web pages obviously store some old URLs. But the slow move that is well known and shows hundreds of 404 responses to internal links tells a unique story.
Look for Clusters
Technical SEO analysis becomes more useful when errors are grouped by location or type. For example:
- Several 404s within one website section
- Repeated 301 redirects from internal navigation
- Multiple 5xx responses from a particular area
- Large numbers of URLs returning unexpected status codes
- Internal links consistently pointing to non-200 URLs
These clusters can help identify whether the problem is related to content, navigation, templates, hosting or URL management.
Indexability Problems Can Follow the Same Pattern
Indexing capacity across the entire network is not consistently constant. Some pages may be deliberately blocked while others are accidentally excluded. A crawl can identify URLs with similar robots directives, noindex tags, or canonical issues.
When Similar Pages Have Different Signals
Suppose that ten pages in the same phase are to be indexed at the same time since the weights of the same pages include non-index instructions. That difference deserves investigation. The problem can come from template rules, CMS setup or even implementation selection with a preference for male or female page errors. A crawler enables comparison of these signals across related URLs so inconsistencies are less complicated to identify.
Patterns Can Reveal Problems With Website Architecture
Technical troubles usually don’t start with metadata or status codes. Sometimes there’s a pattern within the way the pages hook up with each other. Crawls can display sections with surprisingly deep pages, regions with very few internal links or corporate URLs that are hard to get from the size of the main site. This is especially useful for larger websites.
From Individual URLs to Website Sections
A single website with a long crawl path may not indicate a primary problem. If hundreds of critical pages sit several layers deep, however, the site can additionally have architectural trouble. The same advice applies to internal engagement. One page with few internal links can be every day. An entire content class with weak relationships should indicate a structural weak point.
Why Manual Checking Often Misses These Patterns
Manual audits naturally focus on individual pages. The web page is opened, its title is checked, the canonical is reviewed, the links are checked, and the following web page is examined. It can make images for a small website; however, it is difficult to understand repetitive styles as the variety of URLs increases. The crawler collects the same information across pages. That makes it less difficult to organize similar problems and discover relationships among them. The goal is definitely not to create an extended list of errors. The intention is to understand why the same issue is appearing.
How KWT Spider Helps Identify Recurring Issues
KWT Spider approaches technical SEO through structured crawling and diagnostic analysis that helps identify recurring issues. Running slowly can gather statistics, including reputation codes, titles, meta descriptions, canonicals, robot directives, links, indexability codes, and other technical factors. Its diagnostic approaches assist in arranging this information so that recurring issues on the site can be examined with the help of page analysis. For example, instead of noticing a single copy name for the duration of manual testing, slowly moving it can reveal whether duplicate titles are suppressed for three pages or repeated in the order of a particular phase. The same approach can be implemented on redirects, broken links, canonical troubles, missing metadata, hreflang alerts, and other technical search engine optimization elements. This makes slowly driving information useful not only for recognizing mistakes but also for knowing their scope and viable solutions.
Fix the Cause Instead of Repeating the Same Fix
The biggest benefit of identifying patterns is that it changes how technical search engine marketing problems are solved. If one page contains an incorrect canonical, the resolution of that page may be sufficient. If 500 pages have the same incorrect canonical, increasing 500 URLs individually may not be the right answer. A good question is, what is causing these pages to receive the same signal? This could be a template, a CMS configuration, a plugin, an improvement rule, a URL size, or a content workflow. Once the underlying purpose is corrected, many affected pages can be eliminated at the same time.
A Crawl Is More Than an Error List
Technical SEO crawls are usually handled as a tool to find damaged links, metadata, redirects, and other errors. But looking at the facts collectively, their real value will become clearer. Repeated troubles can test relationships that are hard to see from the surface of individuals. The organization of duplicate titles may additionally indicate a template problem. A large number of redirects can also reveal an outdated URL structure. Repeated canonical conflicts can also indicate incorrect implementation. Deep issues throughout the volume can also indicate architectural weaknesses. The sample routinely provides a bigger picture.
Final Thoughts
Technical SEO problems are frequently found in patterns, as websites are built from structures. Templates, CMS rules, navigation systems, plugins, URL conventions, and development choices can directly affect multiple pages. That’s why technical auditing needs to look beyond character URLs. It is useful to find blunders. In addition to understanding whether it is wrong, irrelevant, or repetitive, it is also a valuable opportunity. A full website crawl provides a comprehensive way to recognize these patterns, investigate their underlying causes, and identify technical SEO problems that may affect the entire site.