Sign up with Google
 Sign in with Zoho
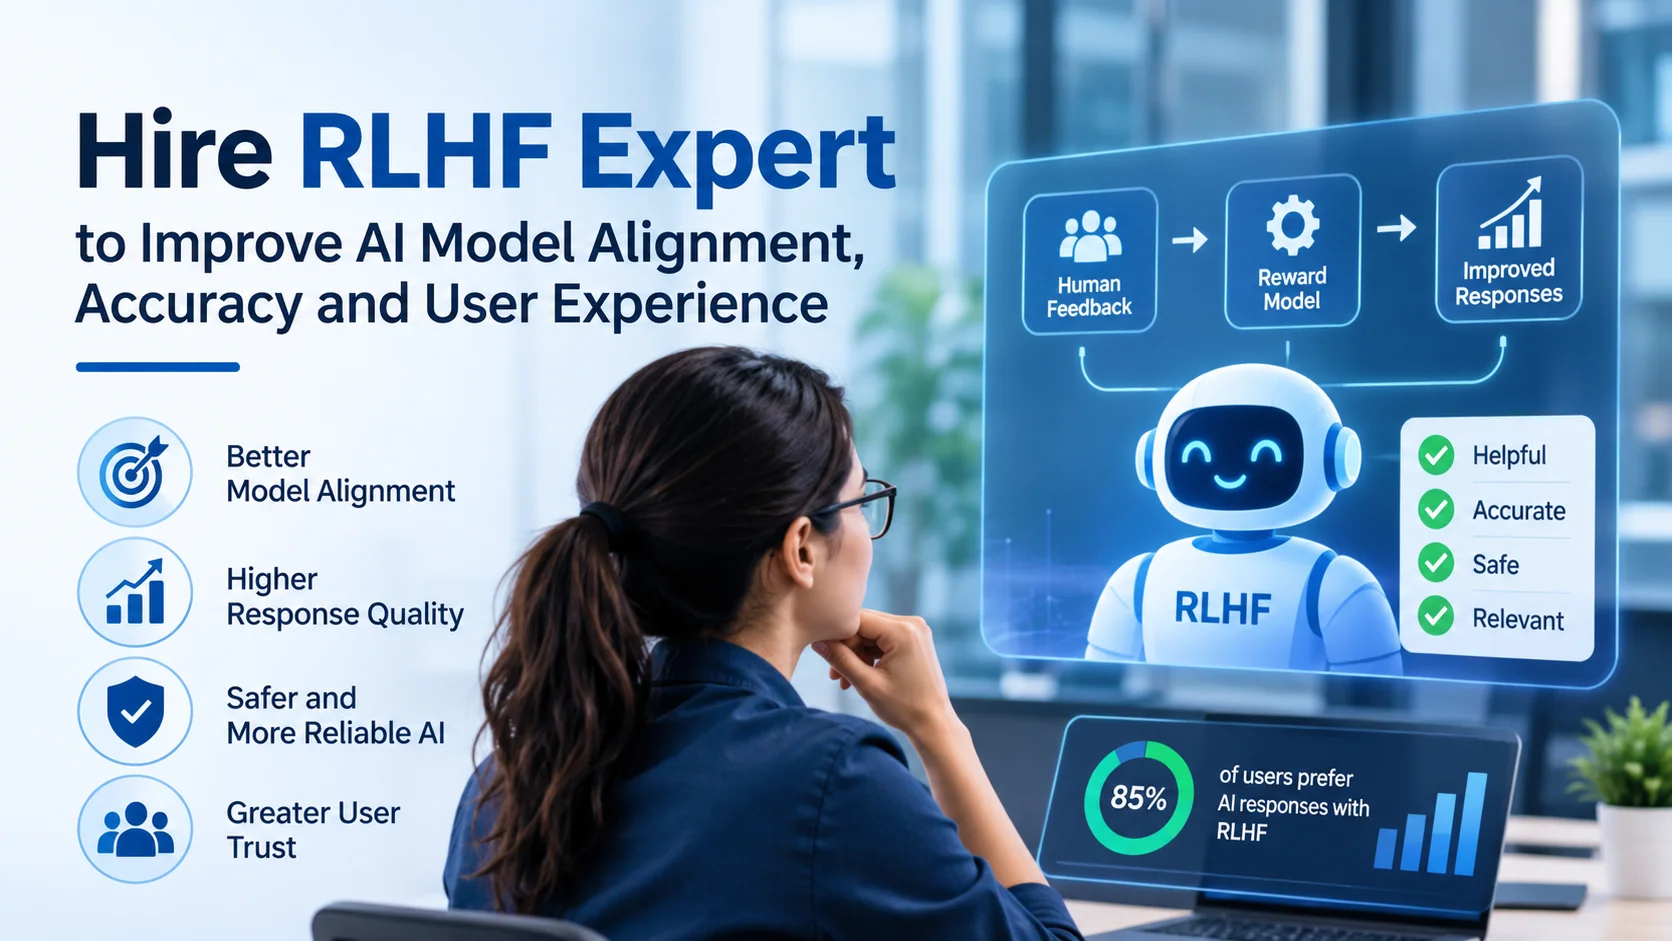
Artificial intelligence models are becoming more capable, but producing technically correct responses is not enough to build reliable AI products. Businesses also need models that understand user intent, follow instructions, avoid harmful outputs and deliver consistent results. This is where the decision to Hire RLHF Expert becomes important for organisations developing advanced AI applications.
Reinforcement Learning from Human Feedback (RLHF) helps improve AI behaviour by using human preferences to guide model responses. It allows development teams to move beyond basic model training and create systems that better match real user expectations.
Why RLHF Matters in Modern AI Product Development
Traditional supervised learning trains models using labelled examples. However, it does not always capture the quality, relevance or usefulness of an answer from a human perspective.
RLHF addresses this limitation through a feedback-based training process. Human reviewers compare model responses, rank their quality and provide preference data. This information helps train reward models, which guide further model optimisation.
For businesses building AI assistants, chatbots, recommendation engines and enterprise automation tools, this approach can improve response relevance and reduce undesirable behaviour.
As generative AI adoption expands, model alignment is becoming an important consideration for product leaders, CTOs and AI engineering managers.
What Does an RLHF Expert Bring to an AI Team?
An experienced RLHF Expert combines machine learning knowledge with an understanding of human evaluation and model behaviour.
Their responsibilities typically include:
- Preference Data Collection: Designing human feedback processes to gather meaningful response comparisons.
- Reward Model Development: Training models to recognise responses that match human preferences.
- Model Optimisation: Applying techniques such as Proximal Policy Optimisation (PPO) and Direct Preference Optimisation (DPO).
- Response Evaluation: Measuring helpfulness, relevance, accuracy, consistency and safety.
- Bias Reduction: Identifying unwanted patterns and improving model behaviour through better feedback.
- Continuous Improvement: Using evaluation results to refine training datasets and model performance.
These capabilities help organisations develop AI systems that are more useful, predictable and aligned with business requirements.
RLHF vs Traditional Fine-Tuning: Understanding the Difference
Traditional fine-tuning improves a model using examples of desired outputs. It works well when organisations have clear, high-quality training data and defined response formats.
RLHF goes further by introducing human preferences into the optimisation process. Instead of simply learning what an acceptable answer looks like, a model can learn which response people prefer when comparing different outputs.
DPO offers another approach by directly optimising preference data without requiring a separately trained reward model and the full PPO workflow.
The right method depends on dataset quality, computational resources, model complexity and product requirements. An RLHF specialist can assess these factors before selecting an appropriate training strategy.
How RLHF Improves Real-World AI Applications
Consider an enterprise developing an AI customer support assistant. Its initial model may provide technically correct answers but struggle with incomplete questions, unclear instructions or sensitive customer requests.
A structured human feedback process can help identify these weaknesses. Reviewers compare alternative responses based on accuracy, clarity, relevance and safety. Engineers then use these preferences to improve model behaviour.
For example, an illustrative pilot might track whether irrelevant responses fall from 20% to 12% after a training cycle. This represents a potential improvement target, not a guaranteed industry benchmark.
Similar methods can support healthcare information platforms, financial research assistants, coding tools and enterprise knowledge systems, with appropriate domain-specific evaluation and safeguards.
Choosing the Right RLHF Expertise for Business Goals
When organisations decide to Hire RLHF Expert, technical knowledge should be considered alongside practical product development experience.
Important areas to evaluate include experience with transformer models, PyTorch, Hugging Face, preference datasets, reward modelling and model evaluation frameworks.
Teams should also examine how candidates approach data quality, reviewer consistency, evaluation costs and safety testing.
In AI development projects, an effective feedback pipeline can be as important as the underlying model architecture. Poorly designed human evaluations may introduce inconsistent preferences, bias and misleading optimisation signals.
The Future of Human Feedback in AI
RLHF remains an important technique for aligning generative AI systems with human expectations. However, the field is evolving towards more efficient preference optimisation, automated evaluation and hybrid feedback approaches.
Businesses that treat model alignment as an ongoing product development activity can make better decisions about quality, safety and user experience.
The real value of RLHF is not simply improving model scores. It is building AI products that respond more reliably to people, support business objectives and earn long-term user trust.