 Sign up with Google
 Sign in with Zoho
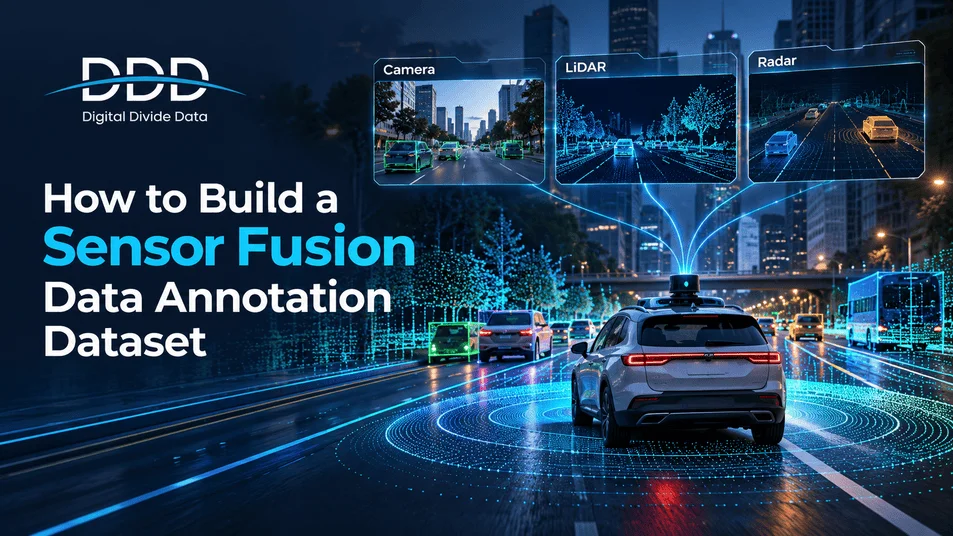
Most sensor fusion data annotation programs that fail do not fail at the annotation stage. They fail at the specification stage, weeks or months before a single label is applied. The annotation schema is incomplete. The scenario coverage is not specified. The calibration process is assumed rather than defined. The format requirements are confirmed too late to affect collection decisions (Source: McKinsey Global Institute, 2023). Sensor fusion data annotation at production quality requires decisions made in the right order, at the right stage, with the right documentation. This post covers the six decisions that determine whether a sensor fusion dataset will support reliable AI training or require expensive rework.
How Do You Build a Production-Ready Sensor Fusion Annotation Dataset?
Building a production-ready sensor fusion annotation dataset requires six sequential decisions: define the annotation schema before collection begins, specify scenario coverage requirements in a scenario matrix, design the collection protocol to meet coverage requirements, select and verify annotation providers against sensor fusion expertise criteria, run the annotation pipeline with mid-project quality controls, and validate the completed dataset before committing it to model training.
Getting stages one and two right is more impactful than getting stages four through six right. An annotation schema that correctly defines every edge case and a scenario matrix that covers every deployment condition produce a dataset that will train reliably even if individual annotation quality is imperfect. A schema with gaps and a scenario matrix with missing conditions cannot be corrected by high annotation accuracy.
How Do You Design an Annotation Schema for Sensor Fusion Data?
The annotation schema is the document that governs every labeling decision made on the dataset. It defines the object taxonomy, attribute specifications, edge case handling rules, occlusion protocol, cross-modal consistency requirements, and escalation process for ambiguous cases. A schema that is ambiguous on any of these produces systematic labeling inconsistencies that are expensive to correct after annotation is underway.
A production sensor fusion annotation schema must include seven components for each object class in the taxonomy:
- Class definition: What physical objects qualify for this label and what do not
- Attribute specifications: Every attribute to be labeled (position, velocity, heading, size, occlusion level)
- Minimum detection threshold: The minimum sensor evidence required to label an object
- Occlusion rules: How to label objects partially visible in one modality and fully visible in another
- Edge case rules: How to handle every foreseeable ambiguous scenario for this class
- Cross-modal consistency rule: How labels in this class must align across all sensor modalities
- Escalation trigger: When to flag a case for senior reviewer rather than annotating independently
Schemas that omit any of these seven components for any object class create labeling gaps that different annotators fill differently. The resulting inconsistency is systematic, appearing on every instance of the undefined scenario across the full dataset.
Edge Case Coverage in Schema Design
Edge cases are the scenarios that appear infrequently in data collection but disproportionately affect model performance in deployment. For autonomous driving sensor fusion, the most consequential edge cases are partially occluded pedestrians, unusual vehicle types (mobility scooters, oversize loads, agricultural vehicles), sensor degradation conditions, and complex junction geometry. For industrial robotics fusion, edge cases include deformable objects, partially assembled components, and objects with reflective surfaces that produce unreliable sensor returns.
Edge cases must be defined in the schema before annotation begins, not identified as problems during annotation review. Every edge case the schema does not define becomes a source of inconsistent labeling across the full dataset.
What Scenario Diversity Does a Sensor Fusion Dataset Need?
Scenario diversity is the distribution of conditions represented in the training dataset. A model trained on a well-annotated narrow scenario distribution will fail in conditions not represented in training, regardless of annotation quality. Scenario diversity must be specified as a structured scenario matrix before data collection begins, not assembled from whatever conditions happen to appear in collected data.
A complete sensor fusion scenario matrix for autonomous driving must specify minimum representation across at least six categories:
The sensor degradation category is the most commonly omitted from scenario matrices and the most consequential for sensor fusion AI. A fusion model that has never seen training examples of LiDAR degraded by heavy rain cannot learn to rely more heavily on radar in those conditions. Training data from degraded sensor scenarios explicitly teaches the model how to reweight sensor modalities when one source is less reliable.
How Active Learning Improves Scenario Coverage Efficiency
Active learning techniques select the most informative data examples for annotation rather than annotating uniformly across a collected dataset. For sensor fusion programs, active learning identifies frames where the current model is most uncertain, which tend to be frames representing underrepresented scenarios. Prioritizing annotation of high-uncertainty frames improves scenario coverage at a lower total annotation cost than uniform sampling across the full dataset. A structured approach to scenario specification and active learning prioritization for multimodal sensor fusion datasets is documented through this resource on multimodal data annotation services for AI programs.
How Much Sensor Fusion Annotation Data Does an AI Model Need?
Data volume requirements for sensor fusion AI depend on the model architecture, the number of sensor modalities, the object taxonomy size, and the required scenario coverage. Published autonomous driving research programs report sensor fusion training datasets ranging from 200,000 to over 2 million annotated frames for full-stack perception models (Source: IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022). Volume is the least important of the four factors. A 200,000-frame dataset with correct cross-modal alignment and full scenario coverage will outperform a 2 million-frame dataset with calibration errors and scenario gaps on every real-world evaluation metric.
Volume Requirements by AI Task
These ranges assume high-quality annotation with full cross-modal consistency. Datasets with systematic annotation quality problems require significantly more volume to compensate for label noise, and even then will underperform a smaller well-annotated dataset on real-world evaluation.
How Do You Manage a Large-Scale Sensor Fusion Annotation Program?
Large-scale sensor fusion annotation programs require governance structures that general-purpose annotation project management cannot provide. The calibration verification process must run on a defined schedule throughout the collection phase, not only at the start. Mid-project sampling must audit annotation quality on a stratified basis across scenario categories, object classes, and individual annotators. Annotation errors detected mid-project are corrected before they compound. Errors detected at delivery require full rework of the affected data.
Mid-Project Quality Control Structure
Production sensor fusion annotation programs run three quality control processes simultaneously throughout the annotation phase:
Weekly calibration audit: A sample of frames is run through cross-modal projection validation to detect calibration drift. Any drift above tolerance triggers a re-calibration verification before annotation continues on data from the affected collection session.
Bi-weekly stratified sampling: Ten percent of completed annotations are audited against a ground truth reference, stratified across object classes, distance bands, and weather conditions. Results feed directly back into annotator calibration sessions within the same week.
Monthly schema review: Edge cases flagged by annotators during the period are reviewed by senior reviewers and resolved into explicit schema updates distributed to all annotators. Schema updates are accompanied by calibration examples showing the correct label for the new rule.
How to Handle Annotation Rework When Errors Are Found
When mid-project sampling detects systematic errors on a specific object class or scenario type, the affected annotations require correction before training. The correction scope depends on the error pattern. A class definition gap that affected all annotations of one class across all annotators requires reannotation of that class across the full dataset. A calibration drift problem that affected frames from specific collection sessions requires reannotation only of the affected session's data. Identifying the error scope precisely before rework begins prevents unnecessary reannotation of unaffected data.
Conclusion
Building a production-ready sensor fusion data annotation dataset is a decision-sequence problem. The decisions made at specification and collection design stages have more impact on final dataset quality than the annotation execution itself. A complete schema, a structured scenario matrix, a calibration-verified collection protocol, and mid-project quality controls are the four factors that determine whether a sensor fusion dataset will reliably train the AI system it is designed for. Organizations that invest the planning effort in the first two stages of the pipeline consistently produce higher-quality datasets at lower total cost than those that rely on annotation execution quality to compensate for specification gaps.